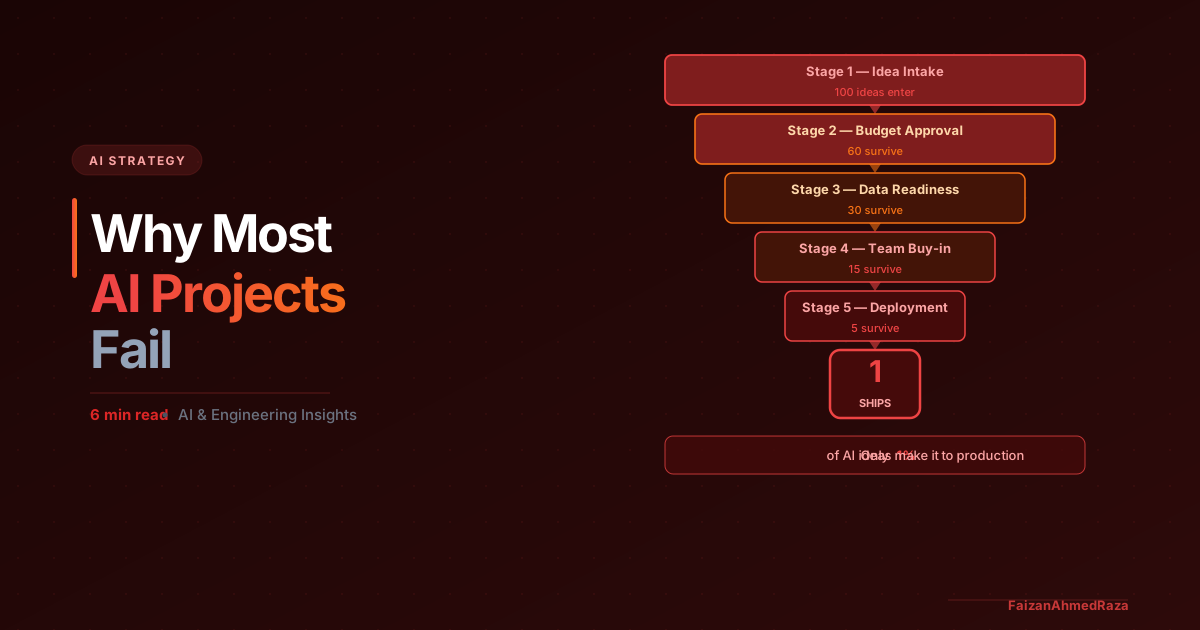
I've worked on enterprise AI systems and research lab deployments, and watched teams on various projects and startups go through the same cycle. The successes and the failures all taught me something — but the failures taught me more.
The uncomfortable truth: most AI projects don't fail because of bad models. They fail long before the model is ever trained.
The Failure Patterns I Keep Seeing
1. Starting with the solution, not the problem
"We need an AI chatbot." "We want to use machine learning on our data." These statements are not problem definitions. They're technology choices made before the problem is understood.
The projects that succeed always start with: What decision are we trying to make better, faster, or cheaper?
In my automotive telemetry anomaly detection work, the system I built started with a very specific question: Can we detect failing components before they cause a fault code? The model came second. The problem framing came first — and it took weeks of conversations with domain engineers to get it right.
2. Underestimating the data problem
In tutorials, data is clean, labelled, and ready. In reality:
- Data lives in 6 different systems with no shared keys
- 40% of records are missing critical fields
- Labels are inconsistent because 3 different people defined the categories
- Historical data doesn't reflect current behaviour
A model is only as good as its training data. Teams often spend months building a model on data that was fundamentally wrong — and only discover this at deployment.
The rule I follow: before writing a single line of model code, spend at least as long understanding and validating the data as you plan to spend training.
3. No clear success metric
What does "good" look like? If the team can't answer this with a number before the project starts, it will never finish — because there's no agreed-upon definition of done.
Precision? Recall? F1? Latency? Cost per inference? Reduction in manual review time?
Pick one primary metric and two guardrail metrics. Write them down. Agree on them. This sounds obvious. It almost never happens.
4. Ignoring the deployment environment
A model that works in a Jupyter notebook is not a production system. The delta between "it works in my notebook" and "it works in production" is where most AI projects die.
Production means:
- Inference latency requirements (can you wait 30 seconds? Probably not)
- Integration with existing systems (REST API? gRPC? Batch job?)
- Monitoring for data drift and performance degradation
- Fallback behaviour when the model is wrong or unavailable
Design for deployment from day one. Ask: where will this model actually run? before you choose an architecture.
5. Skipping the baseline
The question isn't "can we build an AI model for this?" It's "is an AI model better than what we have now?"
I always establish a simple baseline first — usually a rule-based system or a simple statistical model. This gives you:
- A concrete performance target to beat
- A fallback if the ML approach doesn't pan out
- Credibility with stakeholders who are sceptical
From My Own Projects
In my automotive AI thesis research, the first obstacle was not the model but the lack of labelled ground truth. To get it, I ran fault-injection experiments on a hardware-in-the-loop test bench (CRC errors, timing jitter, message drops, sequence faults) and used the results as labelled data.
I then compared the 5-layer framework against an LSTM-Autoencoder and heuristic baselines using precision, recall, F1 and AUROC. Setting up the data and the evaluation before choosing the model is the habit I recommend most.
What Successful AI Projects Have in Common
Looking at the projects that shipped and delivered value, they all share these traits:
- A specific, measurable problem with a clear decision to automate
- Data validated before modelling — understood, cleaned, and representative
- An agreed success metric written down before work starts
- A production-first architecture designed from day one
- A baseline to beat — not just "can we do it" but "can we do better"
- Cross-functional ownership — not just an ML engineer, but a product owner and a domain expert who will actually use it
The Fast Path to a Successful AI Project
If you're starting a new AI initiative, here's the sequence I recommend:
- Write a one-page problem statement. Can you explain it to a non-technical stakeholder in 5 minutes?
- Audit your data. Can you get 1,000 clean, labelled examples? Do they actually represent the production distribution?
- Define success metrics. What number, measured how, means this project is done?
- Build the baseline. What would a rule-based system achieve? This is your floor.
- Prototype fast. You should have a working MVP within 2 weeks. If you don't, the problem is too big or too poorly defined.
AI is enormously powerful — but only when applied to the right problems, with the right data, and with production requirements understood from the start.
If you're trying to figure out whether an AI project makes sense for your business, get in touch. Sometimes 30 minutes of honest scoping can save months of expensive wrong turns.